 Computer Science
Textbook
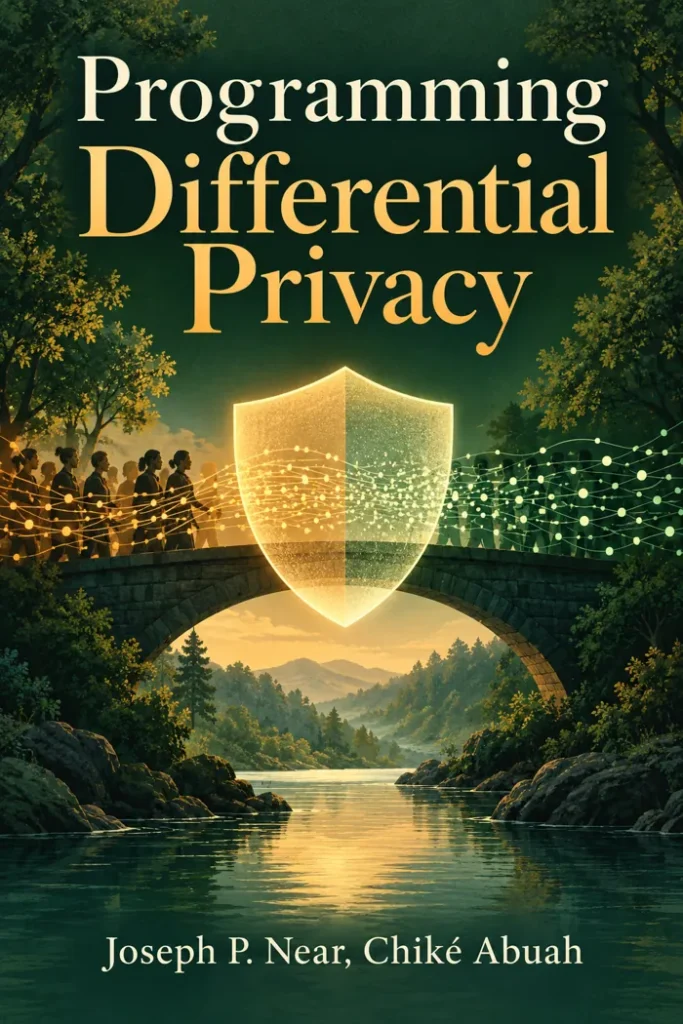
Programming Differential Privacy
Not rated yetRate this bookJoseph P. Near and Chiké Abuah connect differential-privacy concepts with executable programming examples. Their book introduces the challenge of learning from sensitive data while controlling what a release can reveal about individuals.
Read on the publisher’s website. Opens in a new tab.
 Free
About this book
Programming Differential Privacy is an example-driven resource by Joseph P. Near and Chiké Abuah. The reviewed PDF is dated 19 September 2026 and contains 122 pages. Its licence credits the authors in 2025; the PDF date is recorded separately as edition context.
The verified contents move from privacy challenges and limitations of earlier approaches to mechanisms, composition, sensitivity, variants, design, machine learning, local privacy, synthetic data, and implementation limitations. The book combines formal ideas with Python examples rather than treating definitions and implementation as unrelated subjects.
The opening assumes working familiarity with Python, NumPy, and pandas. It also points readers toward background in discrete mathematics and probability. The online format and the print version are generated from the same manuscript, with the web edition providing access to interactive notebook material.
The book text is CC BY-NC-SA 4.0, while its code examples have a separate MIT licence. The guide below covers front matter and the introductory chapter; it does not claim to explain or validate all later algorithms.
Book summary
Joseph P. Near and Chiké Abuah’s Programming Differential Privacy develops privacy through examples, mechanisms, properties, and implementation concerns. The linked PDF is dated September 19, 2026. Sixteen substantive chapters progress from weaknesses in de-identification to formal guarantees, composition, learning, synthetic data, and practical limitations. The central discipline is to state the protected unit, assumptions, and privacy accounting rather than assume that adding randomness automatically creates a guarantee.
Chapter-by-chapter summaries
Introduction
The opening connects practical programming with a formal account of privacy. It explains the learning approach and the need to reason about what an output can reveal. This establishes a distinction between an intuitive sense that data looks anonymous and a property that can be stated and analyzed.
De-identification
Removing obvious identifiers does not necessarily prevent linkage or inference. The chapter uses this limitation to examine the relationship between a released dataset and other available information. Aggregation also requires analysis rather than automatic trust, motivating the need for a guarantee that does not depend on guessing every possible auxiliary source.
k-Anonymity
The chapter explains a grouping-based approach and its generalization choices, then examines weaknesses such as homogeneity. It makes the difference between satisfying a structural condition and protecting the intended sensitive information visible. A dataset can meet a rule while still leaving an important inference available.
Differential Privacy
Differential privacy compares outputs under neighboring inputs and ties protection to a defined unit and adjacency relation. The Laplace mechanism introduces noise calibrated to the query's possible change. The chapter makes the guarantee explicit: privacy depends on the mechanism and parameters, not on whether one particular released result appears harmless.
Properties of Differential Privacy
Sequential and parallel composition and post-processing explain how guarantees behave when mechanisms are combined or outputs are transformed. These properties make system-level reasoning possible. The privacy analysis must follow the actual sequence and overlap of data use rather than examine each query as if no other release existed.
Sensitivity
Sensitivity measures how much a query can change under the chosen neighboring relation. Distance, bounds, and clipping affect that analysis. Underestimating sensitivity can undermine the intended protection, so the chapter connects mathematical calculation with input assumptions that an implementation must actually enforce.
Approximate Differential Privacy
The approximate formulation and Gaussian mechanism extend the toolbox while introducing additional accounting considerations. Vector-valued functions and composition make the role of parameters more visible. Readers should distinguish the guarantee being used and its interpretation rather than treating all mechanisms as interchangeable ways to add noise.
Local Sensitivity
Local sensitivity considers the behavior around a particular dataset, creating both opportunities and difficulties for privacy. The chapter examines approaches including propose-test-release, smooth sensitivity, and sample-and-aggregate. The key question is how a data-dependent choice can be made without exposing the very information the mechanism is meant to protect.
Variants of Differential Privacy
Alternative formulations use different mathematical measures to reason about privacy and composition. The chapter connects these variants with their accounting benefits and relationships. A change in formal language requires understanding the conversion and assumptions, not simply carrying a familiar numerical parameter into a different definition.
The Exponential Mechanism
The exponential mechanism supports selection among outputs using a quality function. It extends private computation beyond releasing a noisy numerical query. The chapter connects a useful choice with the sensitivity of the score and the privacy parameters, making the selection process itself part of the guarantee.
The Sparse Vector Technique
Threshold-based techniques can answer certain patterns of questions with a distinctive privacy accounting structure. The chapter examines above-threshold reasoning and multiple outputs. Correctness depends on the actual information released and the conditions of the construction; an informal resemblance to the algorithm is not sufficient for its proof to apply.
Design and Deployment
Design exercises connect mechanisms with summary statistics, heavy hitters, hierarchical queries, and workloads. The deployment checklist makes operational assumptions visible. A privacy guarantee needs a system that enforces the intended data boundaries, accounting, and implementation behavior rather than a correct formula embedded in an otherwise inconsistent process.
Machine Learning
Private learning connects model training, gradient methods, clipping, and noise. The chapter examines the effect on training and the relationship between an individual contribution and the released model. Utility and privacy need to be assessed together, while preserving the distinction between successful prediction and a justified privacy claim.
Local Differential Privacy
Local approaches alter information before it reaches the central collector. Randomized response and encoding methods illustrate a different trust arrangement. The chapter helps readers compare where randomization occurs and what that changes about the information available for analysis, rather than assuming all privacy models place the same responsibilities on the same party.
Synthetic Data
Synthetic representation can support a release, but generated data is not inherently private. The chapter constructs the connection with formal privacy through mechanisms applied to representations such as histograms. The guarantee follows from the construction and accounting, not from the fact that the output contains newly generated rows.
Efficiency and Limitations
Time, space, random-number generation, and numerical representation affect implementation. The final chapter brings formal reasoning back to actual computation. Practical constraints can change what an algorithm does, so a careful implementation needs to examine whether its numerical behavior preserves the assumptions used in the theoretical explanation.
Study instructions
- For each example, write the protected unit, adjacency relation, query, sensitivity, mechanism, and accounting assumptions.
- Test a program on neighboring toy datasets to understand its behavior without treating an empirical test as a privacy proof.
- Compare utility under different parameters while explaining the guarantee associated with each.
- Use the deployment checklist to identify where a complete system could violate an otherwise correct mechanism's assumptions.
Sources and coverage
This original study guide follows the linked source edition and its chapters or explicitly identified sections. It condenses the main ideas and their relationships; examples and practice directions are for study alongside the complete text. Complete source edition.
About access & copyright
This page provides book information and study material. Full-text access is provided by the original publisher or authorised source; a listing does not grant permission to republish the book.
Read our Library Access & Copyright policyPrivacy purpose
Identify the tension between useful analysis and individual information.
Distinct goals
Explain the introduction’s distinction between privacy and access security.
Preparation
Recognise the programming and mathematics background identified by the authors.
Evidence and guarantees
Separate an observed output from a formally established claim.
Reader ratings & reviews
Share your thoughts
Your review helps other students choose the right resources.
KEEP LEARNING
Your next great read
Computer Science Auditing / Audits
Internal Auditing: A Practical Approach
View Internal Auditing: A Practical Approach — book Cognitive studies
Cognitive Science as String Manipulation
View Cognitive Science as String Manipulation — book Auditing / Audits
Auditing Information Systems
View Auditing Information Systems — book Computer Science
Eloquent JavaScript: A Modern Introduction to Programming
View Eloquent JavaScript: A Modern Introduction to Programming — book Business
Workplace Software and Skills
View Workplace Software and Skills — book Business
Principles of Data Science
View Principles of Data Science — book Computer Science
Introduction to Python Programming
View Introduction to Python Programming — book Computer Science
Introduction to Computer Science
View Introduction to Computer Science — book Computer Science