Data Structure and Algorithms
Computer ScienceTextbook
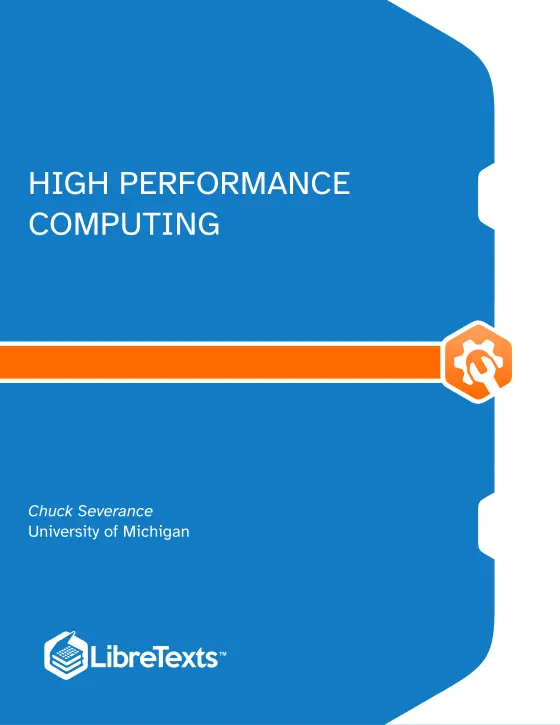
High Performance Computing
Not rated yetRate this bookHigh Performance Computing, presented through Chuck Severance’s LibreTexts text, explains performance through architecture, numerical representation, compilers, measurement, and parallel execution. This guide follows five main chapters and gives separate practice for the two supplied appendices.
Free reading is available at the official source. Opens in a new tab.
 Free
About this book
High Performance Computing, presented through Chuck Severance’s LibreTexts text, explains performance through architecture, numerical representation, compilers, measurement, and parallel execution. This guide follows five main chapters and gives separate practice for the two supplied appendices.
How to study this book
Establish a correct baseline before optimizing. State the workload, input size, hardware, compiler, options, and timing method. Change one factor at a time and compare repeated measurements. Distinguish reduced runtime, numerical accuracy, scalability, and maintainability rather than treating them as the same outcome.
Chapter-wise explanations and study tasks
Chapter 1 — Introduction
The opening frames performance as a relationship among the problem, implementation, and machine. A useful performance claim specifies what work was done and what resource was measured.
Study task: Define a benchmark with a correctness check, workload, input size, and repeatable measurement procedure.
Chapter 2 — Computer Architectures
Memory behavior and floating-point representation strongly influence numerical computation. Access patterns can limit speed, while finite precision changes the interpretation of arithmetic results.
Study task: Compare two traversal patterns for the same calculation and identify a separate numerical-accuracy check.
Chapter 3 — Programming and Tuning
Compiler behavior, timing, profiling, code simplification, and loop optimization provide a measurement-led approach to tuning. A plausible source-code improvement may not change the actual bottleneck.
Study task: Profile a small numerical program, optimize one measured hotspot, and compare the result with the original baseline.
Chapter 4 — Shared-Memory Parallelism
Shared-memory processors permit concurrent work with a common address space. Dependencies, synchronization, and work balance determine whether additional workers improve performance.
Study task: Partition a simple loop and identify the data dependencies that must be removed or synchronized.
Chapter 5 — Scalable Parallel Processing
Language support and message-passing environments connect distributed work with communication. A program’s useful scaling depends on both local computation and the coordination it requires.
Study task: Create a conceptual task-and-message schedule and estimate which part could dominate as worker count increases.
Appendix 6.1 — High-Performance Microprocessors
The microprocessor appendix provides architectural context for the source’s performance discussion. Treat specific processors as historical examples while tracing the mechanisms that affect instruction execution.
Study task: Select an architectural feature discussed in the appendix and explain the class of workload it could help or hinder.
Appendix 6.2 — Assembly Language
Inspecting assembly can reveal how a compiler implements a source operation. The relationship depends on the target and compiler settings, so one listing is not a universal translation.
Study task: Compare a small source loop with a generated or supplied assembly listing and explain one optimization-related difference.
Applied assignment
Prepare a reproducible optimization report for a small numerical workload. Include correctness tests, a baseline, profiling evidence, two controlled changes, repeated measurements, and a numerical-accuracy check. Add a conceptual parallel design and discuss expected communication or synchronization limits without claiming unmeasured speedup.
Suggested reading plan
Read Chapters 1–2 before choosing a benchmark. Use Chapter 3 to measure and tune a serial version, then Chapters 4–5 to analyze parallel opportunities. Consult the microprocessor and assembly appendices to explain observed behavior rather than to substitute for measurement.
Questions for reflection
- What evidence identifies the actual bottleneck?
- Did the optimization preserve the required numerical result?
- Which overhead prevents ideal scaling?
Edition and source notes
This guide follows the LibreTexts export’s five main chapters and its two appendix entries, labeled Appendix C and Appendix B in that order. Hardware, compiler, and parallel-environment examples reflect the source’s period. They support architectural reasoning rather than current purchasing or platform recommendations.
About access & copyright
This page provides book information and study material. Full-text access is provided by the original publisher or authorised source; a listing does not grant permission to republish the book.
Read our Library Access & Copyright policyExplore the contents
Check the chapters covered in this edition.
Visit the official source
See reading, preview or purchase options.
Save for later
Keep this textbook in your saved collection.
Reader ratings & reviews
Share your thoughts
Your review helps other students choose the right resources.
KEEP LEARNING
Your next great read
Computer Science
Relational Databases and Microsoft Access
Relational Databases and Microsoft Access
View Relational Databases and Microsoft Access — bookA Guide to MATLAB
A Guide to MATLAB
View A Guide to MATLAB — book Computer Science
Introduction To MIPS Assembly Language Programming
View Introduction To MIPS Assembly Language Programming — book Computer Science
Java, Java, Java - Object-Oriented Programming
View Java, Java, Java - Object-Oriented Programming — book Computer Science
Think Java - How to Think Like a Computer Scientist
View Think Java - How to Think Like a Computer Scientist — book Computer Science
Think Python - How to Think Like a Computer Scientist (Downey)
View Think Python - How to Think Like a Computer Scientist (Downey) — book Computer Science
Foundations of Computation
View Foundations of Computation — book Algorithms and Data Structures
Discrete-Time Signal Processing First Edition
View Discrete-Time Signal Processing First Edition — book Algorithms and Data Structures