Elementary Calculus
MathematicsTextbook
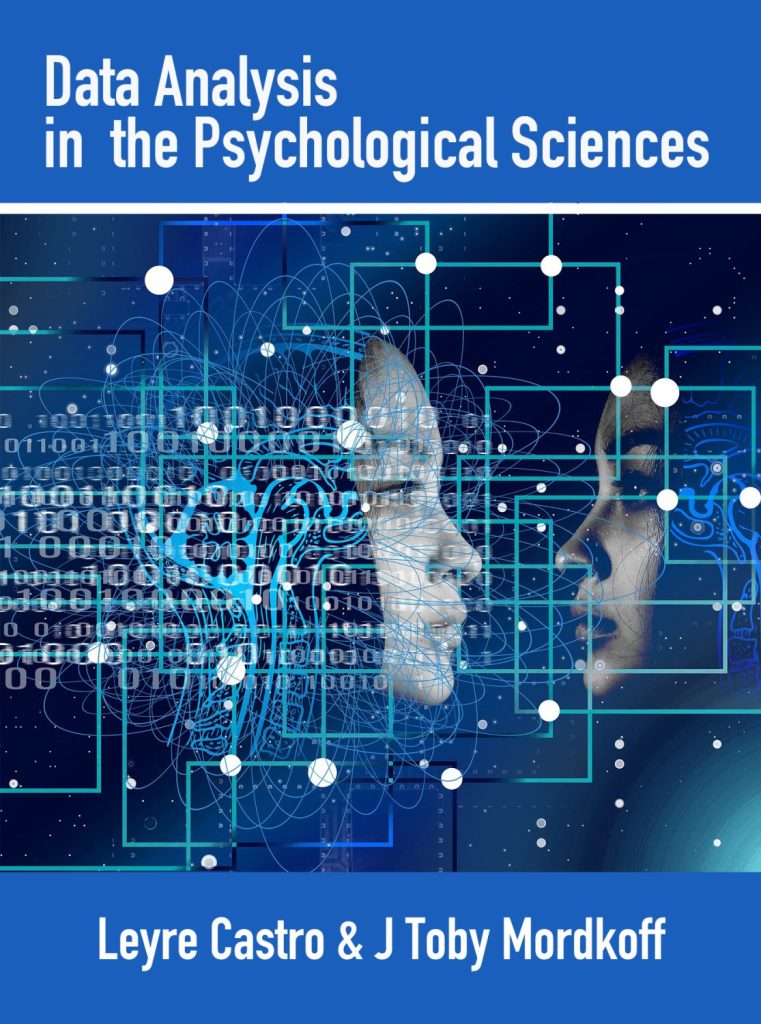
Data Analysis in the Psychological Sciences: A Practical, Applied, Multimedia Approach
Not rated yetRate this bookLeyre Castro and J. Toby Mordkoff’s resource introduces statistical reasoning for psychological data. The reviewed opening connects empirical observation, careful analysis, and the difference between collecting numbers and understanding what they mean.
Free reading is available at the official source. Opens in a new tab.
 Free
About this book
About this book
Castro and Mordkoff introduce psychological data analysis through ten units that pair statistical reasoning with practical work in Excel and R. The book emphasizes organizing data, describing distributions, investigating relationships, and interpreting simple regression. It includes a brief introduction to significance testing but explicitly does not attempt a complete inferential-statistics course. The summaries below keep the conceptual units separate from their software companions and explain what a calculated result can support, what assumptions it depends on, and why an attractive plot or small probability value does not by itself establish a psychological explanation.
The detailed guide below follows the book’s chapter, unit, or section structure. Read it alongside the study instructions and the complete official text.
Book summary
Chapter-by-chapter summaries
Unit 1: Introduction to Statistics for Psychological Science
Psychological research uses observations to evaluate claims about behavior and mental processes. The opening unit distinguishes populations from samples, variables from their observed values, and descriptive statistics from inference. A population is the broader group of interest; a sample supplies the observations actually studied. Descriptive methods summarize those observations, while inference attempts to learn about a population under stated assumptions. The unit also considers measurement and the types of information represented by different variables. These distinctions matter before any computation: numerical labels do not necessarily represent quantities on which arithmetic is meaningful, and a precisely calculated statistic may describe a poorly chosen sample very accurately without generalizing well.
Unit 2: Managing Data
Raw observations usually require organization and documented preprocessing before analysis. The unit discusses formats, storage, and rules that keep a dataset interpretable. Variables need consistent definitions, observations need stable identifiers, and missing entries must be distinguished from meaningful zero values. A useful data structure allows the analyst to identify what each row and column represents without reconstructing the study from memory. Transforming or aggregating values can be necessary, but the distinction between original measurements and analysis-ready values should remain visible. The underlying lesson is that data management is part of scientific reasoning: undocumented changes can alter a result, and an error in structure can propagate through otherwise correct software commands.
Unit 3: Descriptive Statistics for Psychological Research
Descriptive statistics compress a dataset while inevitably leaving out some information. Measures of center describe a typical location, measures of spread describe variability, and distribution shape reveals symmetry, skew, or unusual observations. The chapter compares common summaries and explains why the best choice depends on variable type and the pattern of values. A mean can be strongly affected by extreme observations; a median answers a different question and is less sensitive to their magnitude. Standard deviation and variance describe dispersion around the mean rather than the uncertainty of every possible estimate. Categorical data call for counts or proportions. Numerical summaries should be read with graphs so that important distributional features are not concealed.
Unit 4: Descriptive Statistics with Excel
The Excel unit translates descriptive concepts into spreadsheet operations and short video demonstrations. The task is to organize numerical data, calculate summaries, and make simple plots while checking that selected ranges correspond to the intended observations. A spreadsheet can perform arithmetic quickly, but it cannot decide whether a column is categorical or continuous, whether a missing value was entered incorrectly, or whether a graph has an informative scale. The unit is most useful when each software output is tied back to the definition from Unit 3. Reproducing a calculation on a small subset by hand provides a way to understand what the formula is doing before relying on a larger worksheet.
Unit 5: Statistics with R: Introduction and Descriptive Statistics
R provides a programmable environment in which calculations and data transformations can be recorded and repeated. This unit introduces interaction with the software, objects, data input, and basic descriptive analysis. Unlike an isolated final table, a saved sequence of commands can document how the result was produced. Learning the syntax therefore has a methodological purpose: it helps make decisions inspectable and reduces repetitive manual work. The reader still has to check object contents, variable classes, and missing-data behavior. Errors and unexpected output are information about the mismatch between the requested operation and the actual data. The chapter prepares students to use R for the association and prediction methods introduced later.
Unit 6: Brief Introduction to Statistical Significance
This short conceptual bridge introduces null-hypothesis testing so readers can interpret the later units and research articles. A test evaluates how compatible a statistic is with a specified null model, accounting for sampling variability. A p-value is not the probability that the null hypothesis is true, nor does it measure the size or practical importance of an effect. Statistical significance depends on the analysis and data as well as the underlying relationship, so a large sample can make a small effect detectable. The unit should be treated as an introduction rather than a substitute for a full account of inference, power, confidence intervals, or study design. Interpretation remains tied to the research question and measurement quality.
Unit 7: Correlational Measures
Correlation summarizes association between variables, with Pearson's coefficient focusing on linear relationships. Its sign indicates direction and its magnitude reflects the strength of the linear pattern, but the value alone cannot reveal the whole structure of a dataset. Scatterplots can expose outliers, subgroups, or curvature that complicate a single coefficient. Restricted ranges and unusual points can substantially affect the result. A correlation near zero does not rule out every kind of relationship, and a large correlation does not establish causation. The unit connects the calculation to psychological interpretation: two variables may covary because one affects the other, because a third factor influences both, or because the sampling and measurement process creates a pattern.
Unit 8: Scatterplots and Correlational Analysis in R
The software companion uses experience and task-accuracy data to connect plotting with Pearson correlation. The analyst imports the dataset, identifies predictor and outcome variables, displays paired observations, and requests an association analysis. The output should be read in relation to the graph and the substantive variables rather than as a stand-alone coefficient. The example also shows why the unit of observation must be clear: pairing values incorrectly would create a different relationship even if each column contained valid numbers. A reproducible analysis records the dataset and commands, labels the axes meaningfully, and explains the direction, strength, and limits of the association in ordinary language.
Unit 9: Simple Linear Regression
Regression extends the investigation of association by expressing an outcome as a linear function of one predictor plus unexplained variation. The intercept gives the fitted value when the predictor is zero, and the slope gives the fitted change per predictor unit. Whether the intercept has a useful substantive meaning depends on the scale and observed range. Residuals are differences between observations and fitted values; least squares selects coefficients to minimize their squared total. The unit distinguishes predicting values from explaining causes and relates regression to correlation. A line can summarize a pattern while leaving substantial variation unexplained. Extrapolation beyond the observed predictor range requires additional justification because the same relationship need not continue indefinitely.
Unit 10: Simple Linear Regression in R
The final unit fits a regression to the experience-and-accuracy example and explains the resulting parameter estimates and related output. A useful report translates the slope into the units of weeks of experience and task accuracy, explains uncertainty, and evaluates how well the model describes the observed relationship. Model output should be checked against the data and scatterplot rather than accepted because the software completed successfully. The fitted equation supports predictions within the modeled setting, while residual variation reminds the reader that individual outcomes need not fall on the line. The unit closes the book's progression from a raw dataset to an interpretable model whose claims remain limited by design and measurement.
Supplementary synthesis: From an observation to a defensible conclusion
The ten units form one analytical chain. First identify the population, sample, observational unit, and variable definitions. Preserve raw observations and document preprocessing. Inspect distributions before choosing summaries, and inspect paired observations before choosing an association or regression model. Explain software output in the original measurement units and retain the commands or formulas needed to reproduce it. Finally, distinguish a description of the sample, an inference about a population, and a causal explanation. They are different achievements with different evidence requirements. This synthesis is an additional study aid, not an extra unit in the book.
Study instructions
For a research example, identify the question, variables, observations, and population of interest before choosing a calculation. Keep the observed pattern separate from the conclusion you would like to draw.
When using software, explain the meaning of each input and output in the research setting. Check how missing information or poor measurement could affect interpretation. Use the full source explanation and course requirements before reporting an inferential result.
Questions for reflection
- What do the recorded values actually measure?
- Which conclusion is supported by the observations?
- How could measurement quality affect the analysis?
The study suggestions and questions are independent Academic Master editorial material.
Sources and coverage
These original summaries draw on the source text, including chapter or section introductions and selected explanations, examples, exercises, and review material. They are condensed study guides, not a page-by-page account or a replacement for the complete resource. Additional synthesis sections are identified separately.
About access & copyright
This page provides book information and study material. Full-text access is provided by the original publisher or authorised source; a listing does not grant permission to republish the book.
Read our Library Access & Copyright policyData
Connect values with observations.
Inquiry
Relate hypotheses to empirical evidence.
Interpretation
Explain a result in context.
Quality
Examine the basis of a measurement.
Reader ratings & reviews
Share your thoughts
Your review helps other students choose the right resources.
KEEP LEARNING
Your next great read
Calculus
Measure, Integration & Real Analysis
Measure, Integration & Real Analysis
View Measure, Integration & Real Analysis — bookPrinciples of Social Psychology
Principles of Social Psychology
View Principles of Social Psychology — bookOptimal, Integral, Likely Optimization, Integral Calculus, and Probability for Students of Commerce and the Social Sciences
Optimal, Integral, Likely Optimization, Integral Calculus, and Probability for Students of Commerce and the Social Sciences
View Optimal, Integral, Likely Optimization, Integral Calculus, and Probability for Students of Commerce and the Social Sciences — bookModeling, Functions, and Graphs
Modeling, Functions, and Graphs
View Modeling, Functions, and Graphs — bookTrigonometry
Trigonometry
View Trigonometry — bookIntermediate Algebra
Intermediate Algebra
View Intermediate Algebra — bookProgramming for Computations – Python: A Gentle Introduction to Numerical Simulations with Python 3.6
Programming for Computations - Python: A Gentle Introduction to Numerical Simulations with Python 3.6
View Programming for Computations - Python: A Gentle Introduction to Numerical Simulations with Python 3.6 — book Mathematics
MGF 1131: Mathematics in Context
View MGF 1131: Mathematics in Context — book Applied